 LeCoqRoti
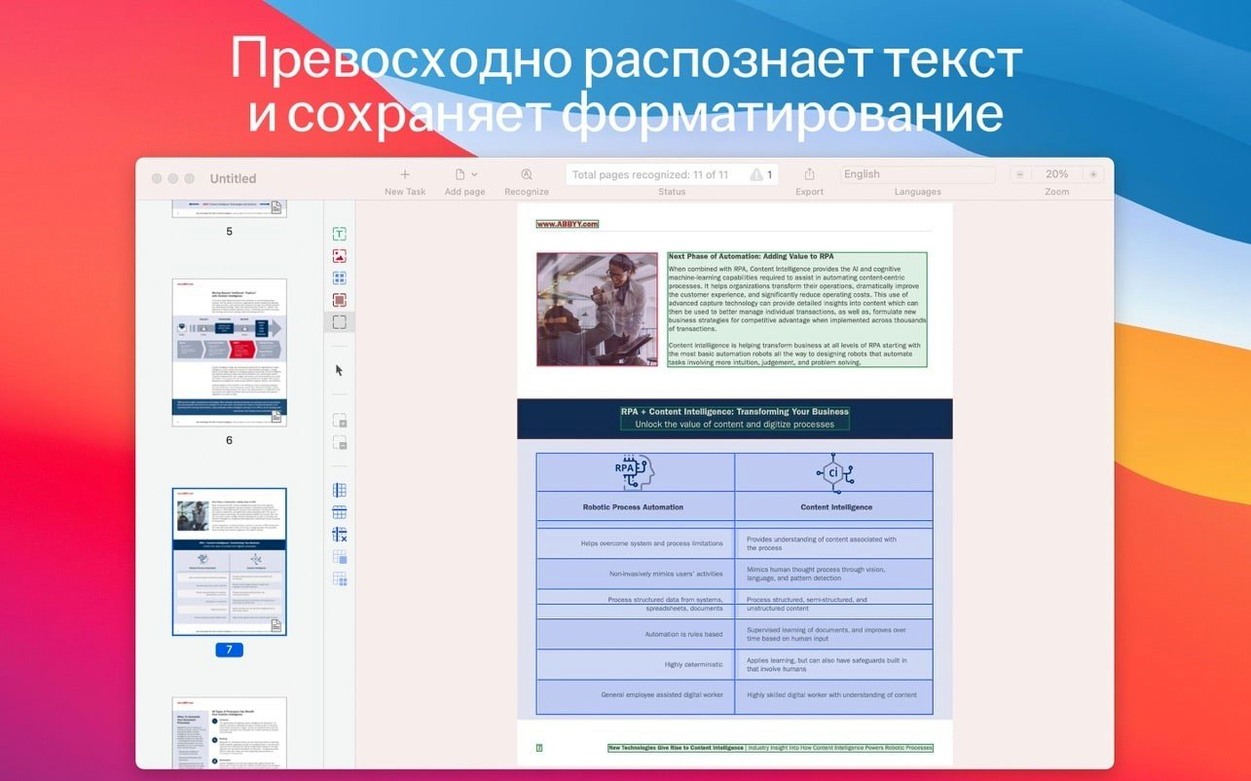
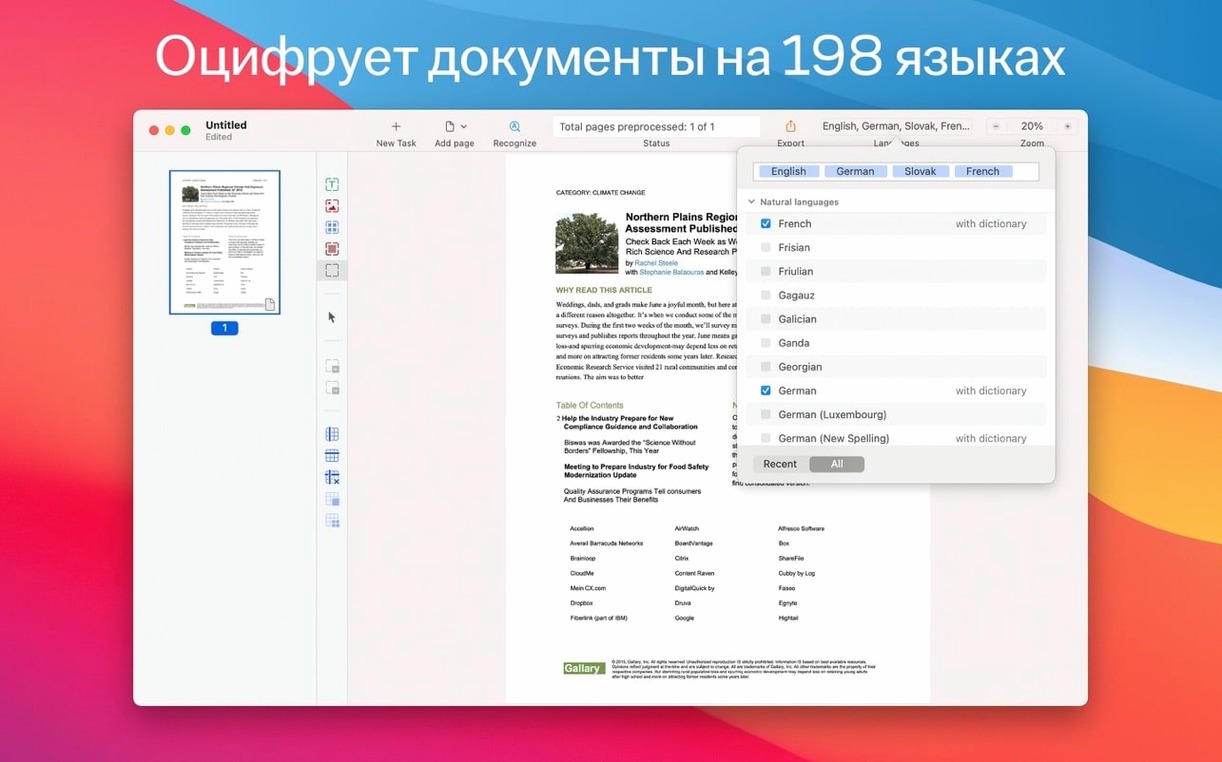
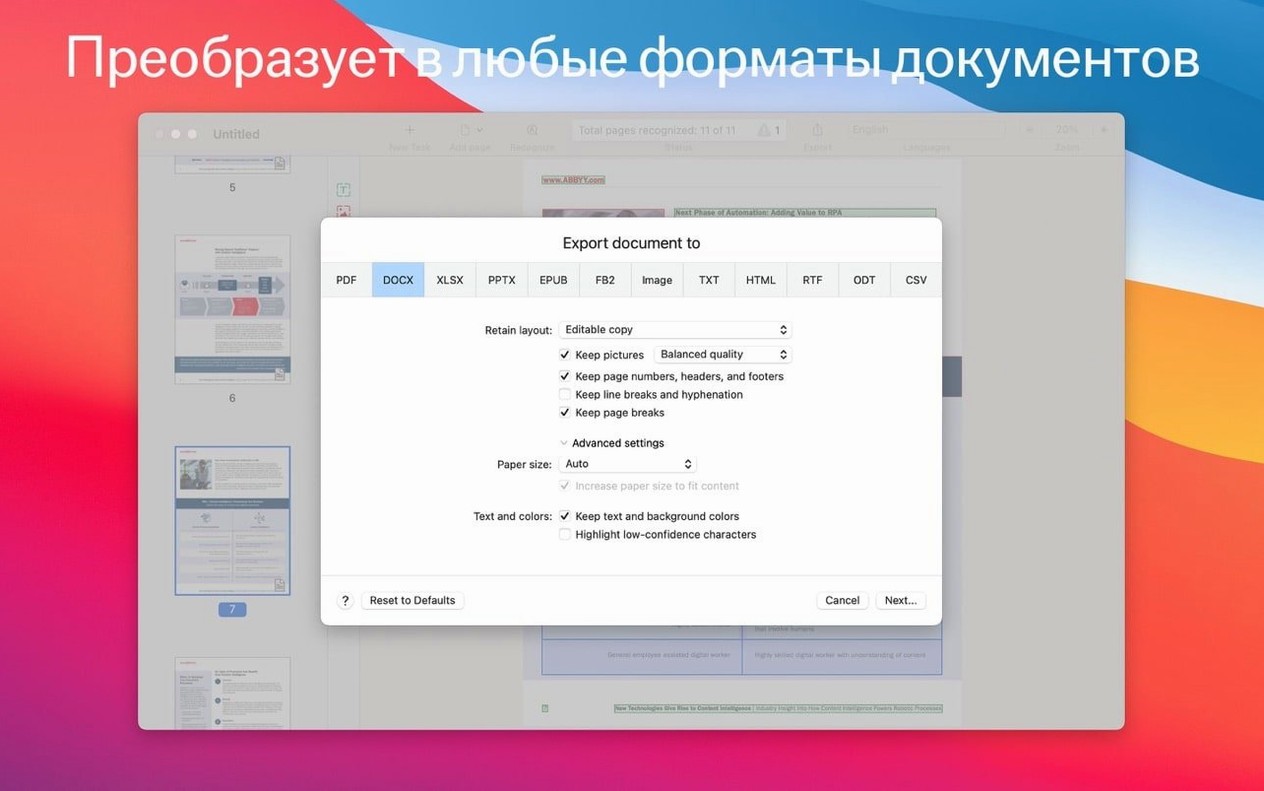
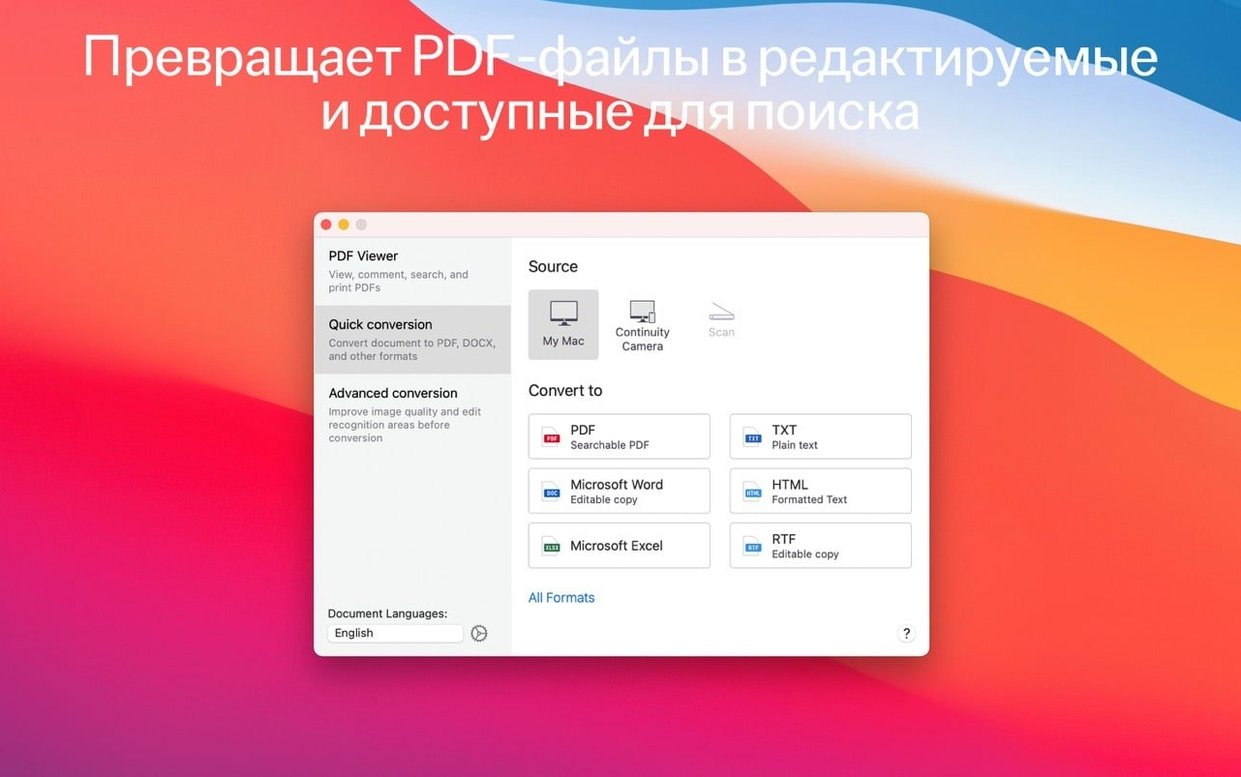
One hundred and ninety-eight recognition languages. That is the figure that sets the tone for ABBYY FineReader PDF, and it means the engine can pull text from a scanned Japanese contract as readily as a faded French typescript. On the Mac, the application runs natively on Intel hardware under macOS 11 Big Sur or later; Apple Silicon is not yet supported, so M-series machines rely on Rosetta 2.
The application bundles a full PDF viewer alongside its OCR editor, so you move between reading, correcting and exporting without leaving the workspace. When a scan lands on your desk, FineReader turns it into a searchable PDF, a Word document or a spreadsheet, preserving the layout until you decide to adjust it. Text locked inside an image-only page can be copied out for citation or translation, and tables are treated as tables, not as a scramble of disjointed lines.
Archival work is well served: you can save to PDF/A for long-term storage or to PDF/UA to meet universal-access requirements. A password-protection option covers the straightforward confidentiality cases, though it sits at the lighter end of document security.
In short: broad language support and a capable editing view make it a practical choice for heavy OCR work, provided your Mac runs an Intel chip or you are comfortable with the Rosetta translation layer.
Performance: deliberate, not lightweight
FineReader does not open in a single bounce. On an Intel MacBook Pro the cold launch takes about six seconds, and the OCR engine holds the CPU at a steady high load while a page is being recognised. That is the trade-off for accuracy: the application parses each character zone, reconstructs tables and compares glyphs against its language models, and it does not rush the job. A ten-page scanned contract in English completes in under twenty seconds on a recent Core i7; switching to a multi-language document with mixed Cyrillic and Latin text adds a few seconds but rarely doubles the time.
Memory use sits around 400 MB at rest with a single document open, rising towards 800 MB during a batch conversion of image-heavy PDFs. The application releases RAM cleanly when you close a file, so it rarely contributes to the creeping swap pressure that some always-open tools cause. Stability has been uneventful in daily use: no document corruption across several weeks of mixed scanning and editing, and only one quiet crash when attempting to open a malformed PDF that Preview also refused.
Rosetta 2 users on Apple Silicon should expect a small warmth penalty on longer OCR runs and a slightly slower first launch while the translation layer caches, but once the engine is running the difference is modest. The interface redraws at 60 fps on an M1, and the scrolling through a recognised page with overlaid text zones feels immediate. For a tool that is not yet universal, the experience under Rosetta is surprisingly civilised.
Legal and academic text extraction: built for verbatim accuracy
The application is built for people whose work turns on the exact words inside a document, not just its general shape. Legal professionals extracting clauses from scanned contracts and academics pulling quotations from old journal PDFs will find the layout retention and table handling save hours of manual retyping. Translators working with multi-language source material can lean on the 198-language recognition rather than maintaining separate tools for each script.
Document managers who need to archive paper records into searchable PDF/A files will appreciate the batch mode: you load a folder of TIFFs and leave it running, returning to a set of properly tagged archive files. The PDF/UA export also makes it a sensible choice for organisations that must meet accessibility mandates, though the tagging is not fully automatic—you still need to verify reading order.
Casual users who only occasionally need to grab text from a screenshot or a single-page scan are better served by lighter tools. FineReader earns its place when the volume is high, the layouts are complex, or the languages are many.
Language selector: stop the engine guessing two alphabets at once
The default recognition language is set to English and Russian, which means the engine will attempt to interpret every character through both models unless you narrow it down. If your documents are monolingual, open the language selector and tick only the languages actually present: recognition speed improves and false positives drop noticeably.
A second worthwhile adjustment is the image processing mode. The default leaves it on automatic, but switching to Text and photos for magazine scans or Text only for clean printed pages gives the engine a clearer instruction and often sharpens the result. The Table detection toggle, buried in the recognition options, is on by default; turn it off when working with prose-only documents to prevent the occasional false table from appearing mid-paragraph.
If you export to DOCX regularly, change the output style from Editable copy to Exact copy only when you truly need a pixel-level reproduction. The editable copy produces a cleaner Word document with fewer floating text boxes, making it easier to reflow text later. For archival output, set the PDF/A conformance level explicitly rather than trusting the automatic choice—PDF/A-2u suits most modern workflows better than the older PDF/A-1b default.
Low-resolution scans: the real reason your OCR looks garbled
The most common early misstep is feeding the engine a low-resolution scan and blaming the OCR when characters come out garbled. FineReader works best at 300 dpi or above; a 150 dpi image of a newspaper column will produce scattered errors no matter how good the recognition model. Rescan at a higher resolution or use the built-in image preprocessing to sharpen the input before recognition.
Another frequent error is ignoring the verification stage. The OCR editor highlights uncertain characters in pale blue, and it is tempting to click straight through to export. Spending two minutes scanning the highlighted zones catches the handful of confusions that even a strong engine makes—rn read as m, or a speck of dust interpreted as a comma—and the time saved in proofreading later is disproportionate.
Beginners also tend to leave the recognition area set to the full page when they need only a single paragraph or table. Drawing a manual recognition zone around the relevant block skips the surrounding clutter and produces cleaner output, especially on densely laid-out pages with marginal notes or watermarks. Finally, do not rely on the password protection as your only security layer; it applies a basic encryption that suits internal drafts but not sensitive client documents requiring certificate-based protection.
Correspondence 0
Take a chair or join the table to send a letter.
No correspondence on this note yet. Letters are read before they appear.